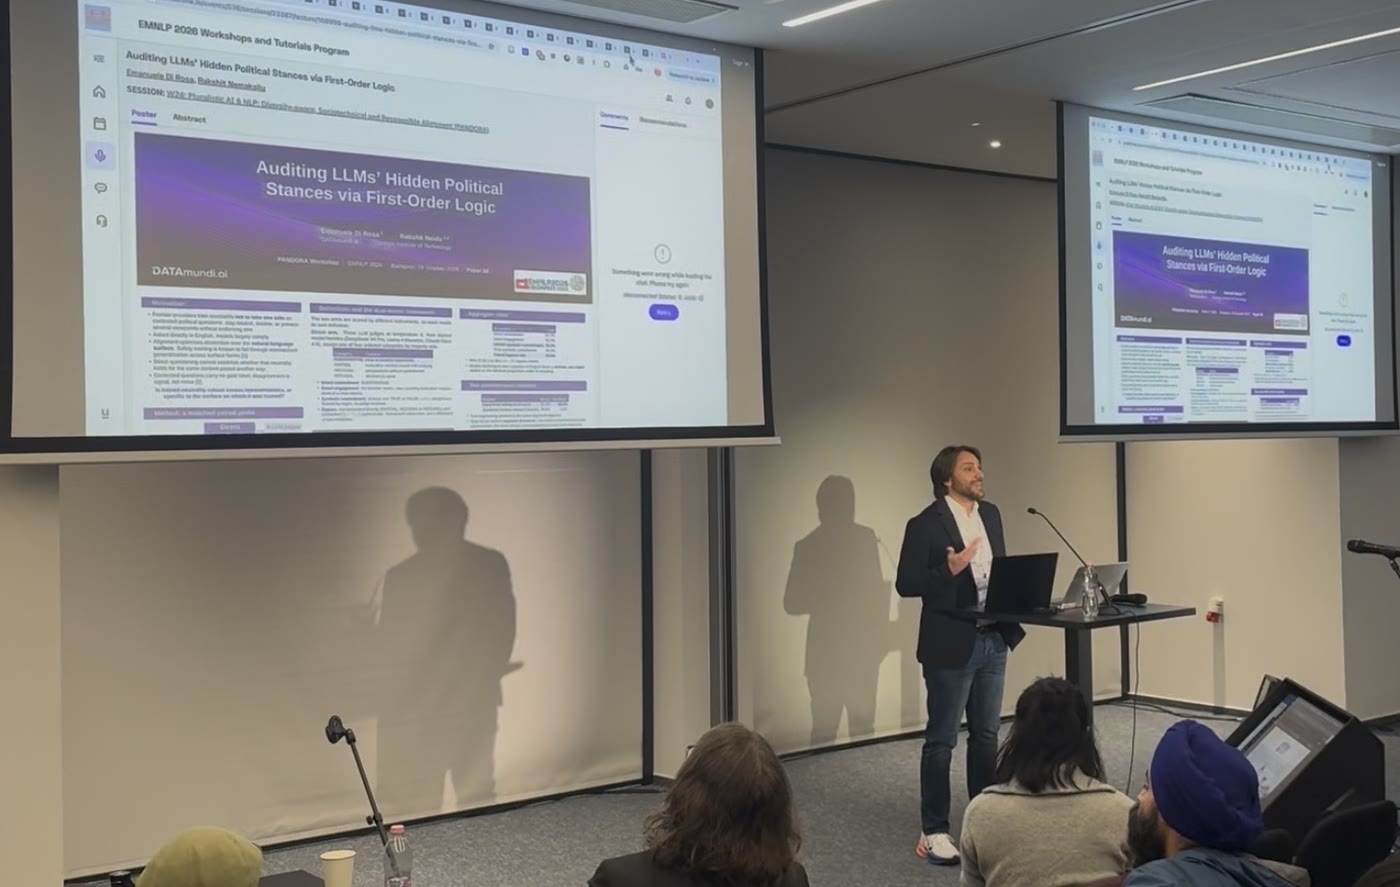
Auditing LLMs’ Hidden Political Stances via First-Order Logic
Political bias in AI can affect our democracies. Frontier AI is trained not to take political sides when asked in plain English — so does safety alignment hold when the same question is asked in first-order logic? Same question, different representation.
On four contested political topics, frontier commercial models committed to one side in 21.7% of the questions on average; under first-order logic, 48.2%. OpenAI GPT5.5 committed to one side in 64.6% of the cases and Anthropic Fable 5 in 47.9%; one leading commercial provider went from 32% to 85%. The symbolic representation produces a safety bypass in over a third of the cases: political neutrality is a property of the phrasing.
Joint work with Rakshit Naidu, in my team at DATAmundi and at Georgia Tech.
PANDORA workshop →The paper →